Turbo-dLLM
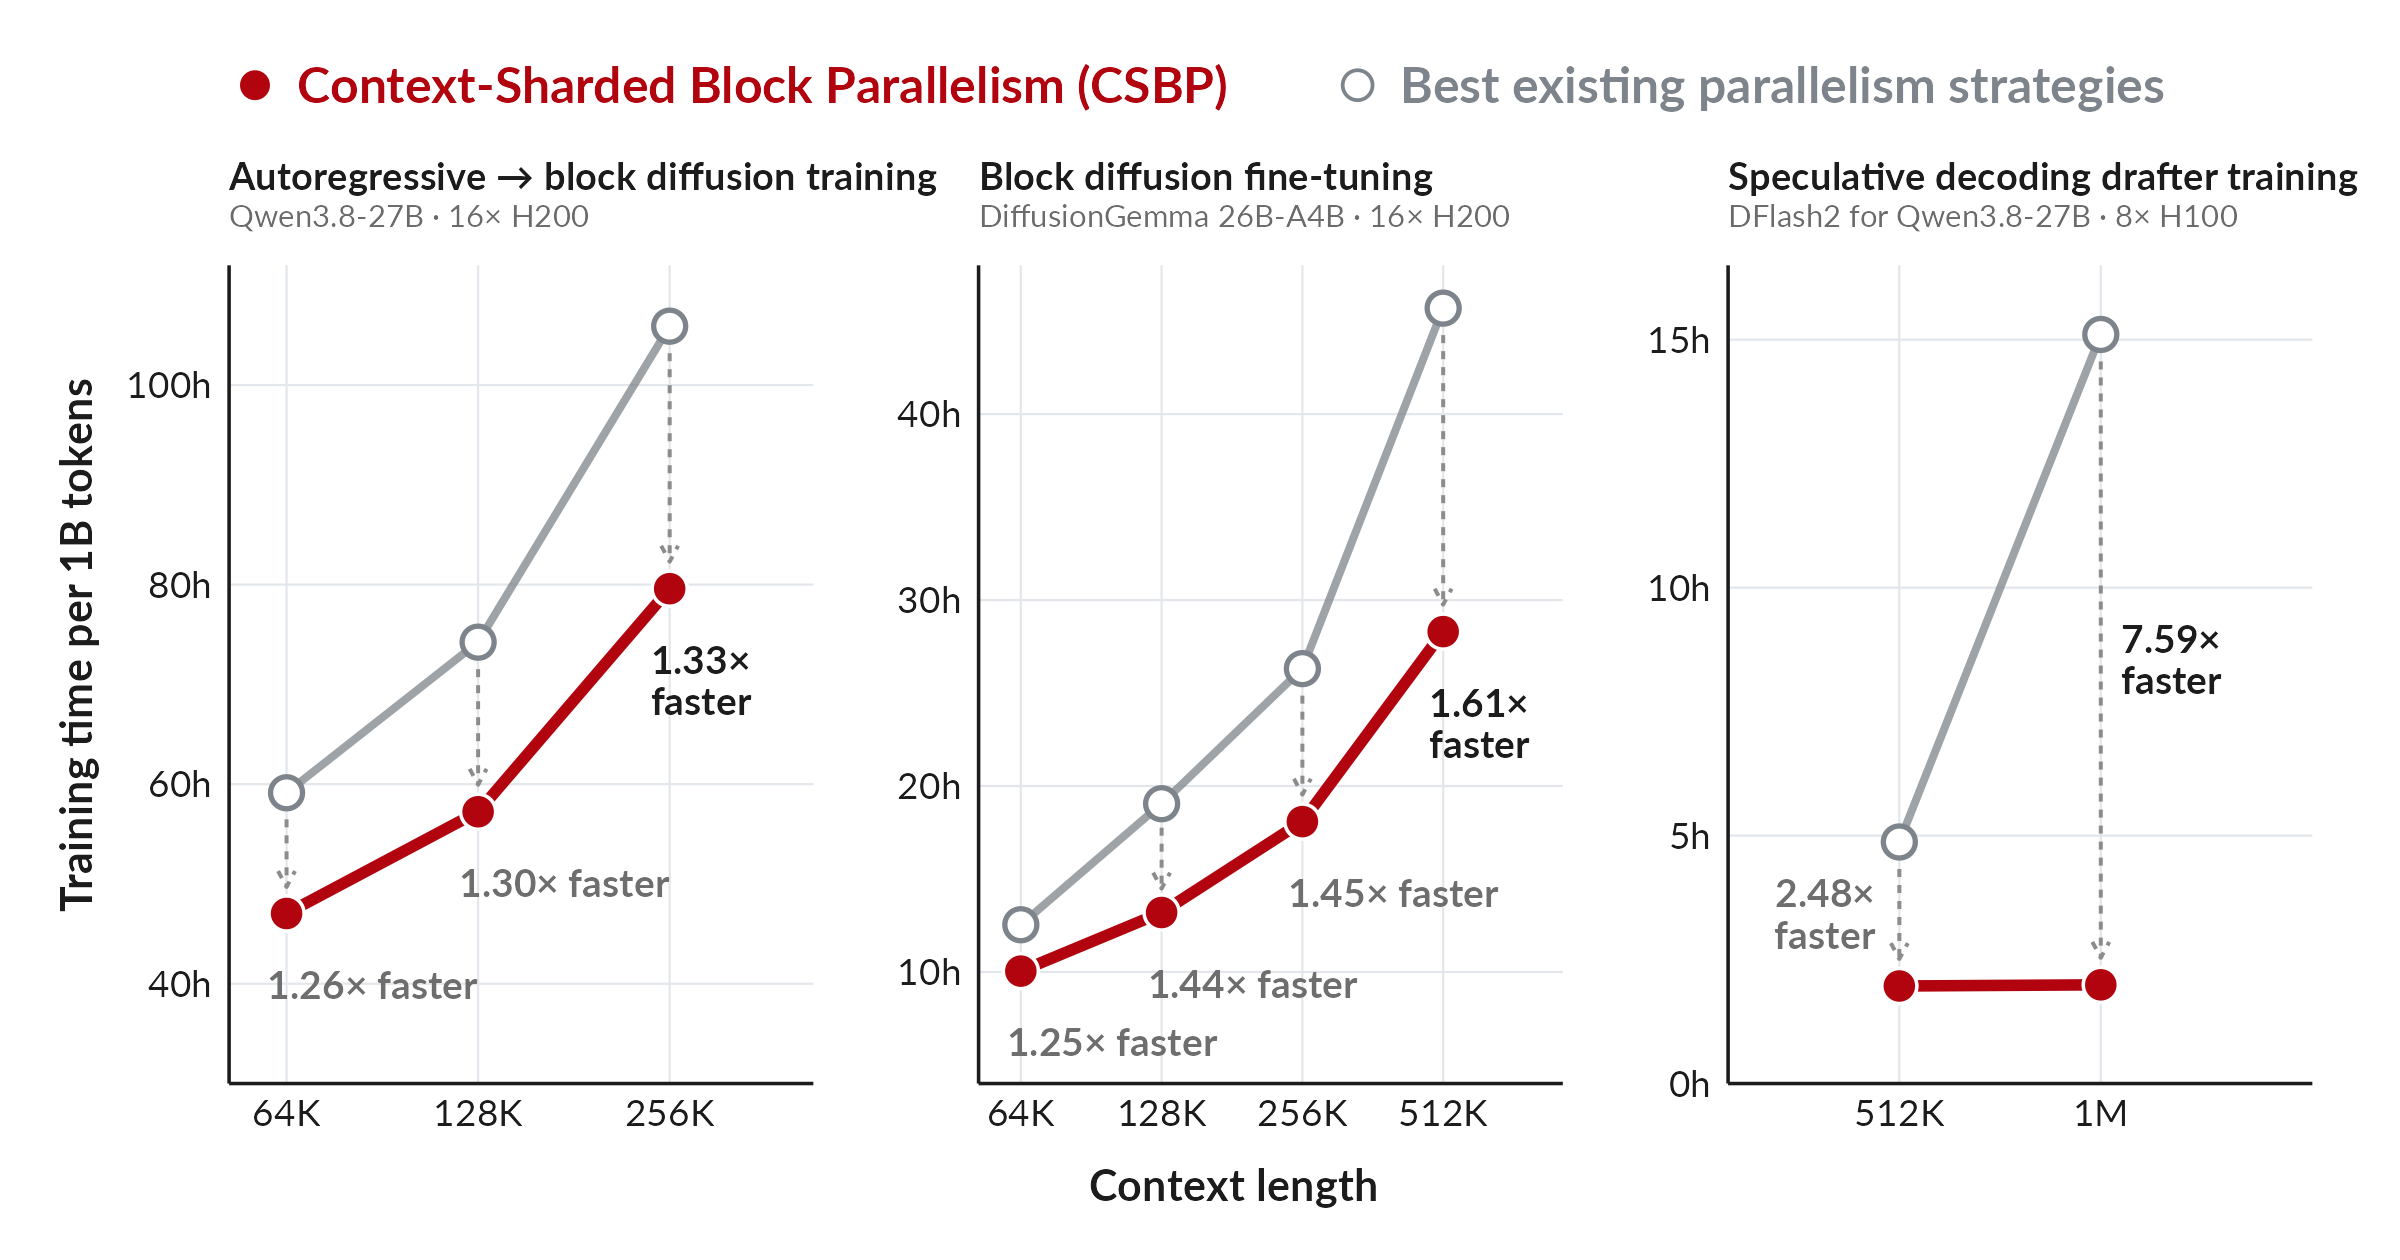
Turbo-dLLM is Up to 7.59× faster long-context diffusion LM training. CSBP is a new distributed parallelism strategy for block diffusion LMs and speculative decoding drafters.. It is ranked #480 on the AI Radar, in AI research, first seen 2 days ago and shared in 1 post (12.1k views).
Visit scalingintelligence.stanford.edu
Block Parallelism for Efficient Distributed Long-Context Diffusion Language Model Training Block Parallelism for Efficient Distributed Long-Context Diffusion Language Model Training We introduce Context-Sharded Block Parallelism (CSBP) , a new distributed parallelism strategy that unlocks significant long-context training efficiency . For diffusion LLMs and speculative decoding drafters, and open-sourced in Turbo-dLLM , our new highly optimized distributed training library. Tarun Suresh * Pranshu Chaturvedi * Hangoo Kang * Parth Shroff Ishan S. Khare Hermann Kumbong Azalia Mirhoseini Stanford University * Equal contribution Read the Paper…
What people said about Turbo-dLLM on X
Check out Turbo-dLLM, our new open-source library for training diffusion LLMs at scale! For example, on 8x H100 GPUs, Turbo-dLLM accelerates DFlash2 speculative-decoder training by 2.48x at 512K and 7.59x at 1M context length. Turbo-dLLM introduces Context-Sharded Block Parallelism, a new paralleism strategy that…
— @Azaliamirh, 2 days ago · 148 likes · see the post
Alternatives to Turbo-dLLM
- academy.dair.ai — Chat with Paper
- arxiv-complete — We’re on a journey to advance and democratize artificial intelligence through open source and open science.
- klpo — KL-Regularized Policy Optimization for Agentic Reinforcement Learning - yifanzhang-pro/KLPO
- recurrent-looped-tranformer — Official Project Page for Recurrent Looped Transformer (RLT) - yifanzhang-pro/recurrent-looped-tranformer
- VLA-Replica — Web home for VLAReplica Benchmark for Robotics
- humanbrain-pollard-h01 — We’re on a journey to advance and democratize artificial intelligence through open source and open science.
Turbo-dLLM in numbers
- Rank on the AI Radar: #480 of 1582
- Shared in 1 post by 1 account: @Azaliamirh
- 12.1k views on those posts
- First seen 2 days ago, last shared 2 days ago
- Pricing seen by Jev: not stated
- Market: AI research
FAQ
What is Turbo-dLLM?
Up to 7.59× faster long-context diffusion LM training. CSBP is a new distributed parallelism strategy for block diffusion LMs and speculative decoding drafters. It was first shared on X 2 days ago and is ranked #480 on the AI Radar.
Is Turbo-dLLM free?
Pricing is not stated on the page we read.
Who shared Turbo-dLLM?
1 account on X, including @Azaliamirh, in 1 post totalling 12.1k views.
Every post is read and classified by Jev (TypeSafe): what it is, which market it belongs to, and whether the link is a real tool. 38k posts from 4.9k X accounts over the last 14 days, 1.6k tools, 19 markets. Collected every 5 minutes, fully re-ranked every hour — last update 2026-09-21 07:04 UTC. Full method.